Building resilient Web3 applications starts with knowing what failure looks like. An endpoint can answer HTTP requests while serving stale blocks or rejecting a required method. RPC health checks should therefore measure data freshness and useful responses as well as availability. RPC failover also needs different rules for repeatable reads and transaction submissions whose outcome is unknown.
Applicable obligations depend on the service, operating model and jurisdiction. A non-custodial label or a particular API does not establish an exemption or replace legal assessment. Document who controls keys, initiates transfers and operates the service, then assess those facts with qualified advisers. Keep technical risk controls and regulatory conclusions separate.
Key Takeaways
- Identify the critical infrastructure vulnerabilities that smart contract audits miss to ensure your application remains functional during intense network congestion.
- Master the implementation of multichain RPC gateways and automated failover mechanisms as the core foundation for building resilient web3 applications.
- Implement dual-pipeline event architecture to maintain total data integrity and successfully navigate the technical complexities of blockchain re-orgs.
- Integrate real-time AML intelligence into your transaction workflow to mitigate regulatory risks and prevent the influx of sanctioned assets into your ecosystem.
- Leverage a unified infrastructure platform and pay-per-call pricing to achieve enterprise-grade scalability without the cost of managing multiple redundant vendors.
The Core Pillars of Web3 Resilience: Beyond Smart Contract Security
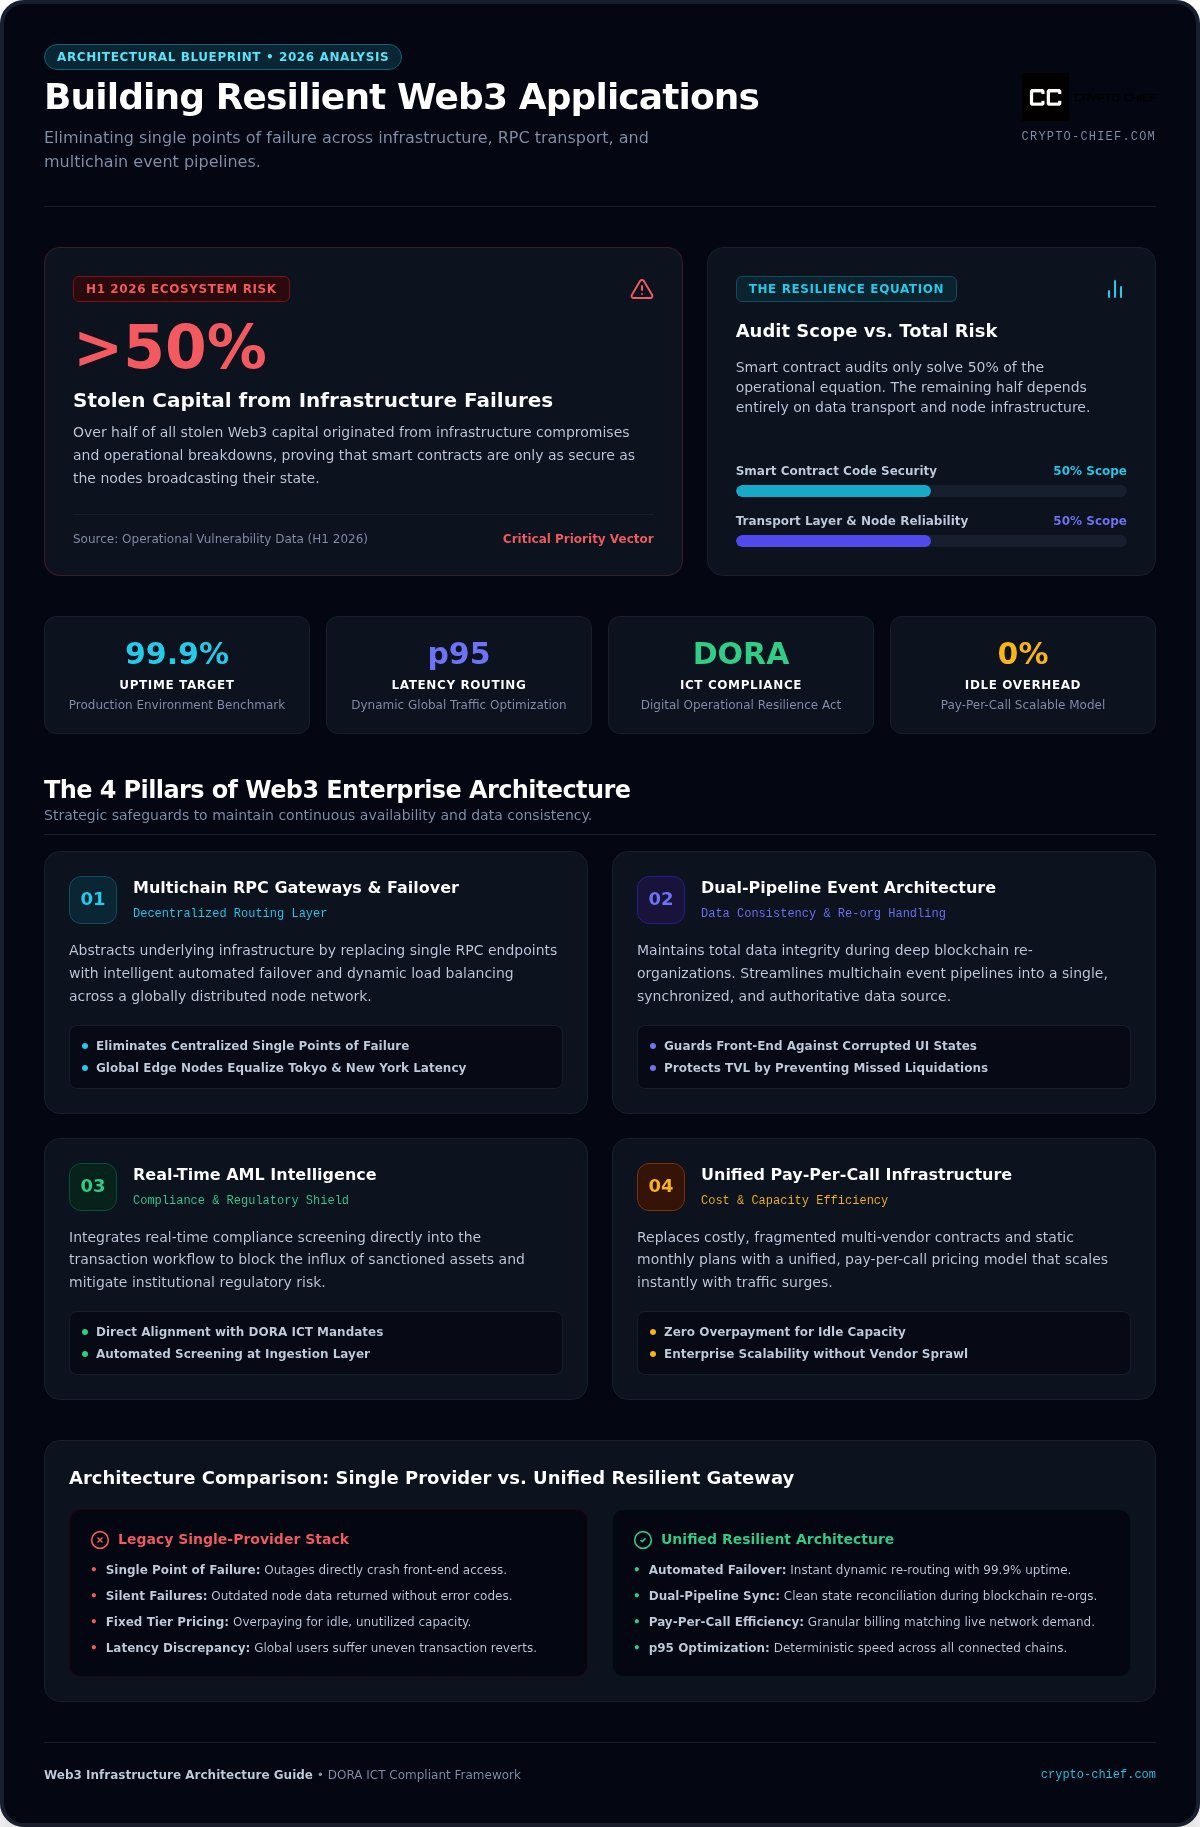
True resilience in Web3 is the capacity to maintain functional consistency even when facing severe network congestion or node failure. While many developers prioritize smart contract security, this focus only addresses half of the operational risk. A secure contract is effectively non-existent if the infrastructure layer fails to deliver its state to the user. Building resilient web3 applications in 2026 requires a holistic strategy that treats infrastructure as a primary security vector rather than an architectural afterthought.
Smart-contract review and infrastructure operations address different failure modes. A code audit does not establish that an RPC endpoint is available or current, and a healthy endpoint does not establish that contract logic is correct. Test both boundaries and keep a recovery plan for stale data, endpoint failures and application-state discrepancies.
The impact of RPC downtime or high latency extends far beyond minor user inconvenience. When a dApp becomes unresponsive, user retention drops immediately; Total Value Locked (TVL) is placed at risk as users lose the ability to manage or exit their positions. Moving toward a unified infrastructure approach allows developers to eliminate fragmented dependencies, replacing a patchwork of third-party services with a single, reliable foundation for building resilient web3 applications that prioritize stability and performance.
Infrastructure vs. Code: Where Resilience Fails
The path from a user's browser to the blockchain is often riddled with single points of failure. Most dApps rely on a single RPC provider, creating a critical bottleneck where even a minor service interruption renders the front-end useless. Silent failures are particularly dangerous; these occur when a node returns outdated or inconsistent data without a clear error code, leading to corrupted UI states and user frustration. Infrastructure resilience is the operational backbone that ensures dApp availability remains constant regardless of underlying network volatility.
The Role of Latency in Financial Web3 Apps
In financial applications, every millisecond of latency translates to measurable risk. High latency delays data propagation, causing arbitrage bots to miss opportunities or, more critically, preventing timely liquidations during market crashes. When the "Time to Consistency" across global nodes fluctuates, users experience transaction reverts that drain confidence. To mitigate these risks, architects are moving toward a Web3 RPC Gateway to ensure low-latency performance. This transition is essential for scaling high-volume applications that require deterministic performance across multiple chains.
Eliminating Single Points of Failure with Multichain RPC Gateways
Relying on a single RPC provider is a strategic liability for high-volume dApps. While dedicated endpoints are standard, they often represent a centralized bottleneck in an otherwise decentralized stack. If your primary provider experiences a service degradation, your application effectively ceases to exist for your users. According to NIST's Blockchain Technology Overview, operational resilience in distributed ledgers depends heavily on eliminating these centralized dependencies. True stability comes from a multichain gateway that abstracts the underlying infrastructure, providing automatic failover and load balancing across a global network of nodes.
In 2026, the standard for building resilient web3 applications has shifted from static, tiered monthly plans to more efficient pay-per-call models. This approach ensures you aren't overpaying for idle capacity during quiet periods while maintaining the ability to scale instantly during market surges. Globally distributed node networks further enhance this by reducing geographical latency; this ensures that a user in Tokyo experiences the same performance as one in New York without requiring custom edge logic on your part.
Architecting for Automatic Failover
A unified RPC gateway acts as an intelligent traffic controller. It monitors the health of various node providers in real-time, using sophisticated health-check algorithms to detect "head lag" or stalled synchronization. When a provider fails, the gateway reroutes traffic without requiring a single line of code change from your team. This offloads the burden of node maintenance to a specialized partner. It allows your developers to focus on product innovation rather than dev-ops firefighting, effectively removing the friction of infrastructure management.
Scaling Across Multiple Chains Simultaneously
Managing separate infrastructure for Ethereum, Solana, and BSC is a recipe for technical debt and operational complexity. Each chain has unique data structures and performance requirements, making a unified API essential for seamless integration. By consolidating these requirements into a single high-performance service, you streamline your backend and reduce potential points of failure when building resilient web3 applications. For those managing complex financial flows, integrating a Crypto Chief Processing API provides a reliable way to handle multichain payments with enterprise-grade stability. If you're looking to maintain this level of performance under your own brand, considering a PSP whitelabel solution can help you deploy a robust infrastructure without the overhead of building it from scratch.
Maintaining Data Consistency: Handling Re-orgs and Real-Time Events
The term "real-time" is often a misnomer when applied to blockchain data. In a decentralized environment, a transaction appearing in the latest block is not a guarantee of permanence. Chain reorganizations, or re-orgs, occur when a canonical chain is replaced by a longer or more heavy version, effectively orphaning previously "confirmed" transactions. For those building resilient web3 applications, treating the latest block as final is a critical architectural error that leads to double-spending risks and corrupted database states.
Managing these fluctuations requires a sophisticated event-handling strategy. On high-throughput chains like Polygon PoS, re-orgs can historically reach depths of 32 to 128 blocks, necessitating a deep confirmation buffer before treating state as canonical. Even on Ethereum, where the Pectra hard fork has optimized performance, deterministic finality still requires approximately 13 to 19 minutes. Maintaining data integrity during these windows is essential for meeting the standards outlined in the FinCEN convertible virtual currency advisory, which emphasizes the need for accurate transaction monitoring and risk mitigation.
EventStream vs. Polling: A Resilience Comparison
Constant polling is an anti-pattern for resilient applications. It creates unnecessary load on RPC endpoints and often misses events that occur between poll intervals. Webhook-based event streaming provides a far more reliable alternative. By pushing data directly to your backend, webhooks ensure that your application receives every event even during periods of network instability. For a deeper dive into setting up these systems, refer to our Real-Time Blockchain Webhooks guide. This approach allows you to build a speculative UI for immediate user feedback while maintaining a secondary, canonical pipeline for settled data.
Solving the Multichain Data Normalization Problem
Every blockchain utilizes unique block times, event formats, and finality rules. Building resilient web3 applications that span multiple ecosystems usually involves managing three or four different data structures simultaneously. A unified API simplifies this "Data Resilience" layer by normalizing disparate chain data into a single, actionable format. This abstraction layer prevents logic errors in cross-chain dApps by ensuring that your smart contract interactions are based on consistent, verified data regardless of the underlying protocol's specific quirks. Normalized data acts as a filter, removing the noise of network-specific artifacts and allowing your core application logic to remain clean and predictable.
Strategic Risk Mitigation: Integrating AML Intelligence and Compliance
Resilience is frequently discussed in terms of uptime, but in 2026, it equally refers to the ability to withstand regulatory and systemic shocks. When "dirty" crypto, which includes funds linked to sanctioned entities or exploiters, enters your protocol, it creates a cascade of operational risks. These range from front-end blacklisting by major wallet providers to the complete freezing of liquidity pools by centralized stablecoin issuers. For those building resilient web3 applications, integrating automated risk assessment is no longer a legal luxury; it's a technical necessity to prevent total application failure. Risk management is resilience.
Document the operating facts: key control, signing authority, initiation of transfers and the interfaces the team operates. Use those facts when assessing the service model. A technical architecture label cannot establish the applicable regulatory outcome.
Real-Time Risk Scoring for dApp Protection
Implementing a robust AML Intelligence API allows your backend to evaluate the risk profile of every incoming address before a transaction is broadcast. This data enables the creation of "Circuit Breakers," which are automated logic gates that halt interactions with addresses exceeding a specific risk threshold. This protects your protocol's liquidity and ensures your application doesn't become a conduit for illicit activity. In the event of a network-wide exploit, funds tracing becomes a vital tool for post-incident resilience, allowing you to identify and isolate compromised assets before they spread through your ecosystem.
Compliance as a Scalability Feature
Institutional investors require certainty. They need to know their capital won't be commingled with sanctioned funds. Building trust through transparent risk detection and reporting transforms compliance from a hurdle into a competitive advantage. Utilizing tools like the Crypto AML Risk Detection API serves as a pillar of enterprise resilience, providing the audit trails and real-time monitoring necessary for long-term growth. To secure your protocol against systemic risk today, integrate our AML Intelligence solutions into your stack.
Scaling with Confidence: Implementing a Unified Web3 Infrastructure
The transition from a fragmented toolset to a unified platform is a decisive step in building resilient web3 applications. Relying on a five-vendor stack-one for RPC nodes, another for AML, a third for event streaming, and so on-dramatically increases your failure surface area. Every additional integration is a potential point of failure that requires its own maintenance cycle and monitoring logic. By consolidating these functions into a single high-performance engine, you eliminate the friction of multi-vendor management and reduce the risk of a "cascading failure" where one tool's outage breaks the entire pipeline.
Cost efficiency plays a pivotal role in this architectural shift. The pay-per-call model allows you to scale resilience without the burden of massive upfront costs or expensive tiered subscriptions that charge for capacity you don't use. It ensures your infrastructure costs align perfectly with your actual usage, whether you're handling a quiet development phase or a high-volume mainnet launch in 2026. Crypto Chief simplifies the path to building resilient web3 applications by providing this unified foundation, allowing you to scale with professional confidence.
Reducing Technical Debt with Unified APIs
A single integration for RPC, AML intelligence, and real-time event streaming minimizes technical debt. Instead of rewriting your infrastructure layer every time you expand to a new chain, a unified API abstracts the complexity of multichain data normalization. This future-proofs your application, allowing you to deploy on emerging networks with minimal code changes. For developers ready to begin their integration, the Crypto Chief Documentation provides comprehensive quick-start guides to streamline the process.
Checklist for 2026 Mainnet Launches
Before moving to production, architects should verify the following:
- Failover Redundancy: Are you using an active-active RPC gateway rather than a single provider?
- Data Integrity: Does your event pipeline handle re-org depths specific to your target chains?
- Regulatory Readiness: Is real-time AML screening integrated into your transaction lifecycle?
- Global Latency: Are your nodes distributed to ensure consistent performance for a global user base?
Conclusion: The Future of High-Availability dApps
Infrastructure uptime is no longer a luxury; it's a non-negotiable requirement for any dApp that intends to survive in 2026. As the ecosystem matures, the focus shifts from basic functionality to enterprise-grade reliability. Crypto Chief acts as your silent partner, handling the complex problems of node maintenance and data consistency so you can focus on your product. By choosing a unified foundation, you ensure that your application remains stable and secure. Start building with Crypto Chief's Unified API today to secure your position in the future of decentralized finance.
Future-Proofing Your Web3 Architecture
The landscape of 2026 demands more than just audited code; it requires a structural commitment to operational uptime. By moving away from fragmented vendor stacks and embracing a unified infrastructure, you eliminate the single points of failure that threaten user trust and protocol stability. Building resilient web3 applications is a continuous process of balancing high-speed performance with rigorous data consistency and real-time AML intelligence. Success in this environment belongs to those who view infrastructure as a strategic asset rather than a background utility.
You can now leverage a high-performance global RPC network and non-custodial processing to secure your protocol without the overhead of managing complex node arrays. With enterprise-grade AML risk detection built directly into your workflow, you gain the freedom to focus on your core product while we maintain the engine. Scale your dApp with Crypto Chief’s unified Web3 infrastructure and build with the confidence of an enterprise leader. Your vision deserves a foundation that never blinks.
Classify failures before retrying through another endpoint
Retry a bounded read with backoff when the error is transient, and check whether a rate limit calls for slower traffic. After a submission timeout, retain the signed payload and derived hash and query its status before creating another transfer. A second endpoint is useful evidence, but a different answer can reflect propagation delay. Compare providers at a common block when diagnosing data disagreement.
Test stale nodes and replay gaps during an outage drill
An outage drill should include a stale block head, a throttled log query, a dropped connection and duplicate event deliveries. Record how long recovery takes and whether the application can rebuild missed state from its stored cursor. For blockchain reorg handling, retain block hashes and a reversible record of recent updates. Review Crypto Chief RPC coverage and event streaming against the exact recovery workflow you test.
Frequently Asked Questions
What are the most common causes of downtime for Web3 applications?
Downtime often stems from a reliance on a single RPC endpoint that becomes a central point of failure. When that provider experiences service degradation or network congestion, the dApp loses its connection to the blockchain. Additionally, "head lag," where a node falls behind the current block height, can serve stale data that causes transaction reverts. These infrastructure bottlenecks are more frequent causes of failure than smart contract bugs themselves.
How does a multichain RPC gateway improve dApp resilience?
A multichain RPC gateway acts as an intelligent abstraction layer that routes traffic across multiple independent node providers. It utilizes real-time health-check algorithms to detect underperforming or stalled nodes, automatically rerouting requests to the most stable endpoint. This architecture ensures that your application remains online even if several providers fail simultaneously. It's a fundamental strategy for anyone building resilient web3 applications who requires high availability across different blockchain ecosystems.
Can building resilient web3 applications actually reduce my infrastructure costs?
Yes, resilience doesn't have to be expensive. By consolidating fragmented tools like RPC, AML intelligence, and event streaming into a single unified platform, you eliminate the overhead of managing multiple vendor contracts. Using a pay-per-call model further optimizes spending by ensuring you only pay for the specific requests your application makes. This replaces costly, underutilized monthly tiers with a scalable pricing structure that aligns perfectly with your actual user traffic.
What is the difference between polling and event streaming for data consistency?
Polling is a reactive method where your server repeatedly asks a node for updates, often missing events or wasting bandwidth. Event streaming, particularly through webhooks, pushes data to your backend the moment a transaction is detected. This proactive approach is superior for maintaining data consistency because it provides a continuous stream of information. It allows developers to build more responsive interfaces while ensuring that every on-chain event is captured and processed correctly.
Why is AML intelligence considered part of application resilience?
Risk intelligence can support a review workflow by supplying address or transaction signals. Define who interprets an alert and what the application can actually control. A frontend check cannot prevent direct interaction with a public contract, and a score does not guarantee detection or an uninterrupted service. Keep risk review and technical availability as distinct operating responsibilities.
How do I handle blockchain re-orgs when building a payment-focused application?
Handling re-orgs requires a dual-pipeline strategy that distinguishes between speculative and canonical data. For a payment-focused application, you should only consider a transaction settled once it reaches a "finalized" or "safe" block tag, which takes about 13 to 19 minutes on Ethereum in 2026. This prevents the risk of double-spending or processing payments on a chain that is later orphaned. Using unified APIs simplifies this by providing normalized status updates across multiple chains.
What is the pay-per-call model and how does it help with scaling?
The pay-per-call model involves purchasing prepaid API token balances that are deducted per request made to the platform. This helps with scaling by removing the financial barriers of high-tier monthly plans that often go unused. As your dApp grows, your costs scale linearly with your traffic, providing a predictable and efficient way to manage resources. It's particularly effective for building resilient web3 applications because it allows for massive bursts in traffic without requiring manual plan upgrades.
Do I need to host my own nodes to meet an availability target?
Measure response-time percentiles, errors and data freshness from the regions and methods your application uses. A lightweight latest-block read and a historical log query are different workloads. Confirm current availability commitments, supported regions and incident procedures directly; a generic latency or uptime claim does not establish performance for your application.